Tech Square
2022.07 - PresentScreens
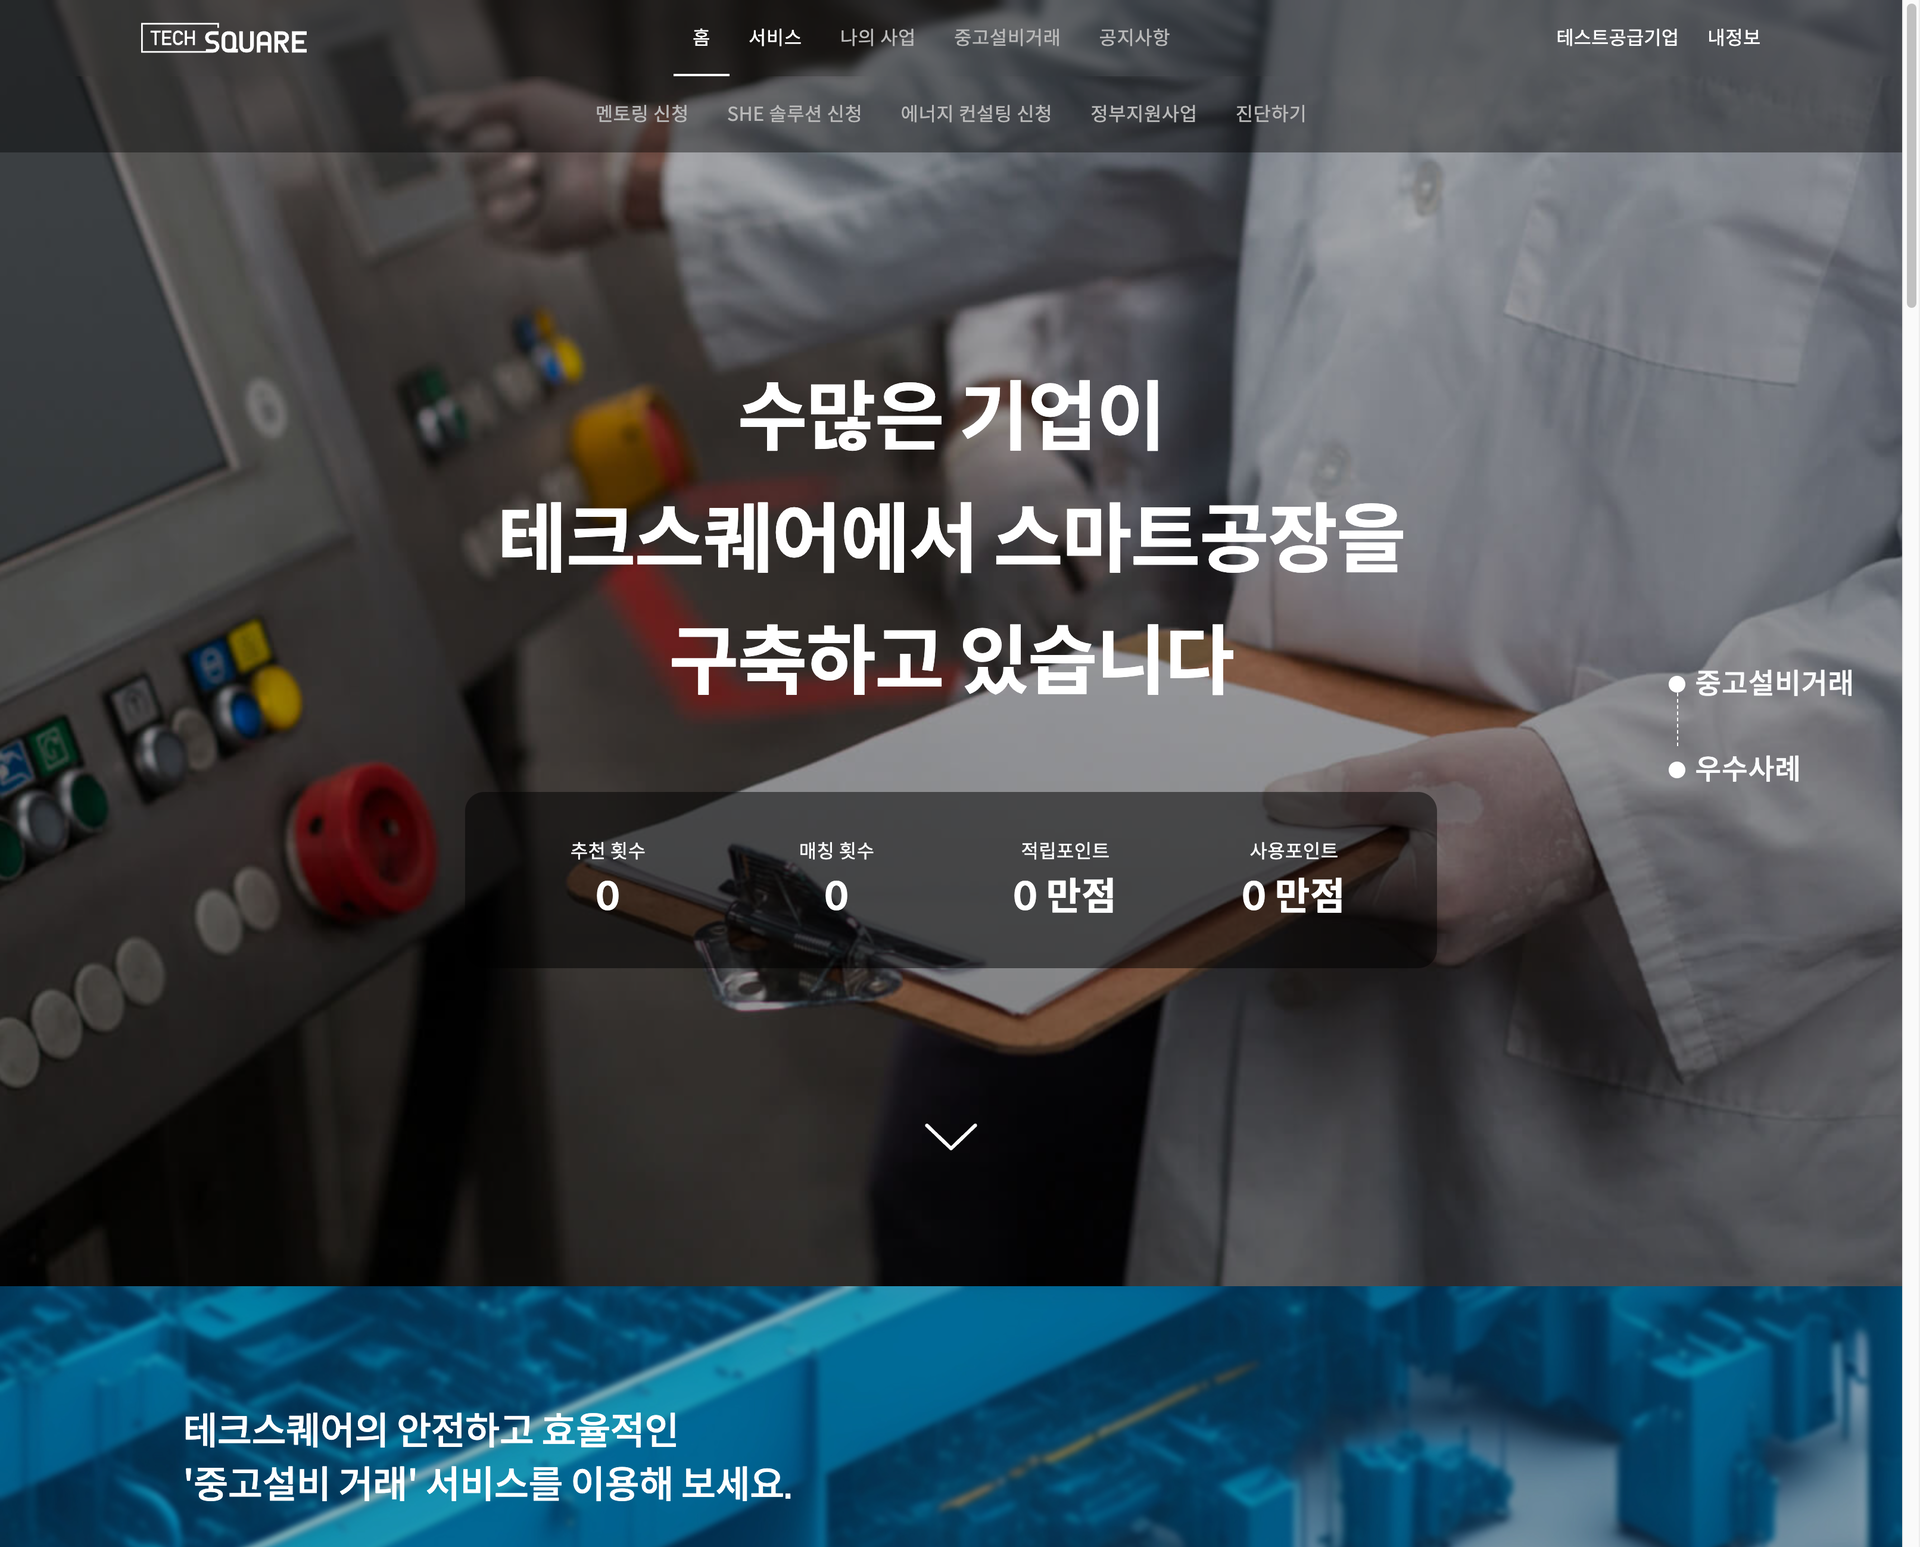
Overview
A B2B manufacturing platform where demand and supply companies can find smart-factory partners and use mentoring, used-equipment trading, and operational information services.
Role & Tech Stack
Node.js, Express, TypeORM, MySQL, Vue 3, AWS, GitLab CI/CD
Achievement 01
Taking Part in Rebuilding a Java 8 System as a Node.js Platform
- Background & Cause
- Tech Square's existing system ran on Java 8 and had quality and maintainability limits. A new platform aligned with the Vue 3 user and admin channels was needed.
- Decision & Rationale
- I did not take part in the transition decision. I joined afterward, co-built the Node.js, Express, and TypeORM system, and handled data migration. We unified the front-end and language ecosystem to reduce collaboration boundaries. Old and new systems ran in parallel to verify functions and data before we took over operations.
- Outcome
- The platform transitioned without operational interruption. After the build, I operated and improved the API and the user and admin channels together with one outsourced engineer.
- Retrospective
- An operational-system transition needs more than new technology. It finishes reliably only when data migration, parallel operation, and handover-completion criteria are designed together.
Achievement 02
Standardizing Data-Integrity Boundaries with a Shared Transaction Layer
- Background & Cause
- Recommendation requests were sometimes received twice, and recommendation status sometimes diverged from actual progress. Changes belonging to one business operation had to be grouped in one transaction, with a consistent rule for duplicate requests and status changes.
- Decision & Rationale
- Using only what the ORM provides is faster early on, but transaction boundaries scatter across controllers as the business grows. Because I saw this as a long-running service, I accepted the initial cost and built a shared SQL and transaction layer on TypeORM. A change that is one business command is grouped in one transaction. Work that a rollback cannot undo, such as external API calls and email, was moved outside the transaction. For duplicate requests, I first considered raising the transaction isolation level. But a higher isolation level does not remove the duplicate command itself and only increases lock contention. So I put a unique constraint on the business key and added a command identifier and a check of the current state.
- Outcome
- The three-layer structure and the shared transaction layer are maintained across 61 business services. Transaction handling did not diverge even after the business grew.
- Retrospective
- The purpose of shared transactions is not code reuse but consistent success and failure boundaries for each business operation.
Achievement 03
Improving Repeated Lookups by Restructuring Queries
- Background & Cause
- As member, company, and mentoring data grew, each list item triggered another lookup for related information. Query combinations also became more complex as search criteria increased.
- Decision & Rationale
- Rather than increase time limits or add indexes indiscriminately, I replaced repeated lookups with joins and batched queries. A parameter-binding query builder organized dynamic search conditions, improving both execution structure and input safety.
- Outcome
- Repeated lookups were reduced, search criteria can be combined safely, and lists and Excel downloads now share the same lookup rules.
- Retrospective
- For slow lookups, inspect result sets and repetition counts first. Correct the query structure, then choose the indexes that are actually needed.
Achievement 04
Moving Local Files to a Shared S3-Based File Flow
- Background & Cause
- Uploaded files were tied to server-local paths, so browsing and download behavior changed with the environment. Separate exceptions had accumulated for PDFs, Excel files, and images.
- Decision & Rationale
- To separate server instances from file lifecycles, I moved to S3 but kept a period in which both old and new paths could be read. Shared utilities centralized upload, retrieval, deletion, and original-filename restoration. Storage changes therefore did not spread through business code.
- Outcome
- Notices, reports, quotations, and images now use one storage approach, reducing environment-dependent file paths and duplicate handling.
- Retrospective
- A file-store migration is a data migration, not only a copy of objects. It must preserve existing keys, original names, and retrieval-path compatibility.
Achievement 05
Strengthening Authentication and Input Boundaries in Stages
- Background & Cause
- Browser-accessible authentication tokens, dynamic SQL, HTML input, and multiple upload paths each created different security risks.
- Decision & Rationale
- I moved JWTs to HttpOnly cookies to prevent direct browser-script access and converged concurrent 401 responses into one token refresh. Parameterized SQL and allowlist validation for HTML and files applied defenses appropriate to each boundary. Authentication, data, input, and file boundaries were handled separately.
- Outcome
- Authentication flows were unified across user and admin channels. That reduced exposure paths leading to script input, SQL injection, or risky file rendering.
- Retrospective
- Security is not solved by one filter; authentication, input, data, and file boundaries must each be checked and narrowed in stages.
Achievement 06
Building Observability by Connecting Log Fragments into Request Flows
- Background & Cause
- Service-level `console` logs alone made it difficult to connect how far one request had progressed through API and data processing.
- Decision & Rationale
- Instead of adding more logs, I standardized all sources on a structured logger and assigned a correlation ID to each request. Connecting an OpenTelemetry traceId preserves the log format while tracing request flow beyond service boundaries.
- Outcome
- Operations can now narrow problem locations by request rather than search individual log entries separately.
- Retrospective
- Observability depends less on log volume than on whether different records can be connected into the same request flow.
Achievement 07
Making Secrets and Local Development Reproducible
- Background & Cause
- Environment-specific configuration and secret-management approaches were scattered. An interrupted local database tunnel also made application connectivity unstable.
- Decision & Rationale
- For a small team with mixed staffing, I chose Infisical over Vault because its adoption barrier was lower. Docker Compose standardized the runtime environment. The database tunnel became a separate process with disconnection detection, exponential-backoff reconnection, and duplicate-run prevention.
- Outcome
- Secrets are separated from code and deployment files, and developers can reproduce the same startup procedure. Tunnel failures can recover without restarting the entire application.
- Retrospective
- Standardizing a development environment is not only about aligning tools. It means defining failure and recovery for configuration, secrets, and external connections.
Achievement 08
Automating Repetitive Work with Batch and Notification Pipelines
- Background & Cause
- When people repeatedly load external data, check statuses, and notify owners, omissions and processing delays can occur.
- Decision & Rationale
- I batched bulk data instead of sending per-record requests to reduce the number of database requests. Cron jobs and notification flows were configured by business condition. Duplicate execution, empty results, and environment-specific sending are handled separately. That prevents automation from creating unnecessary work under exceptional conditions.
- Outcome
- Company-data ingestion and operational notifications now run on defined conditions and schedules. That reduces repeated confirmation work for owners.
- Retrospective
- Batch automation is defined less by periodic execution than by safely handling duplicate processing, empty results, and partial failures.